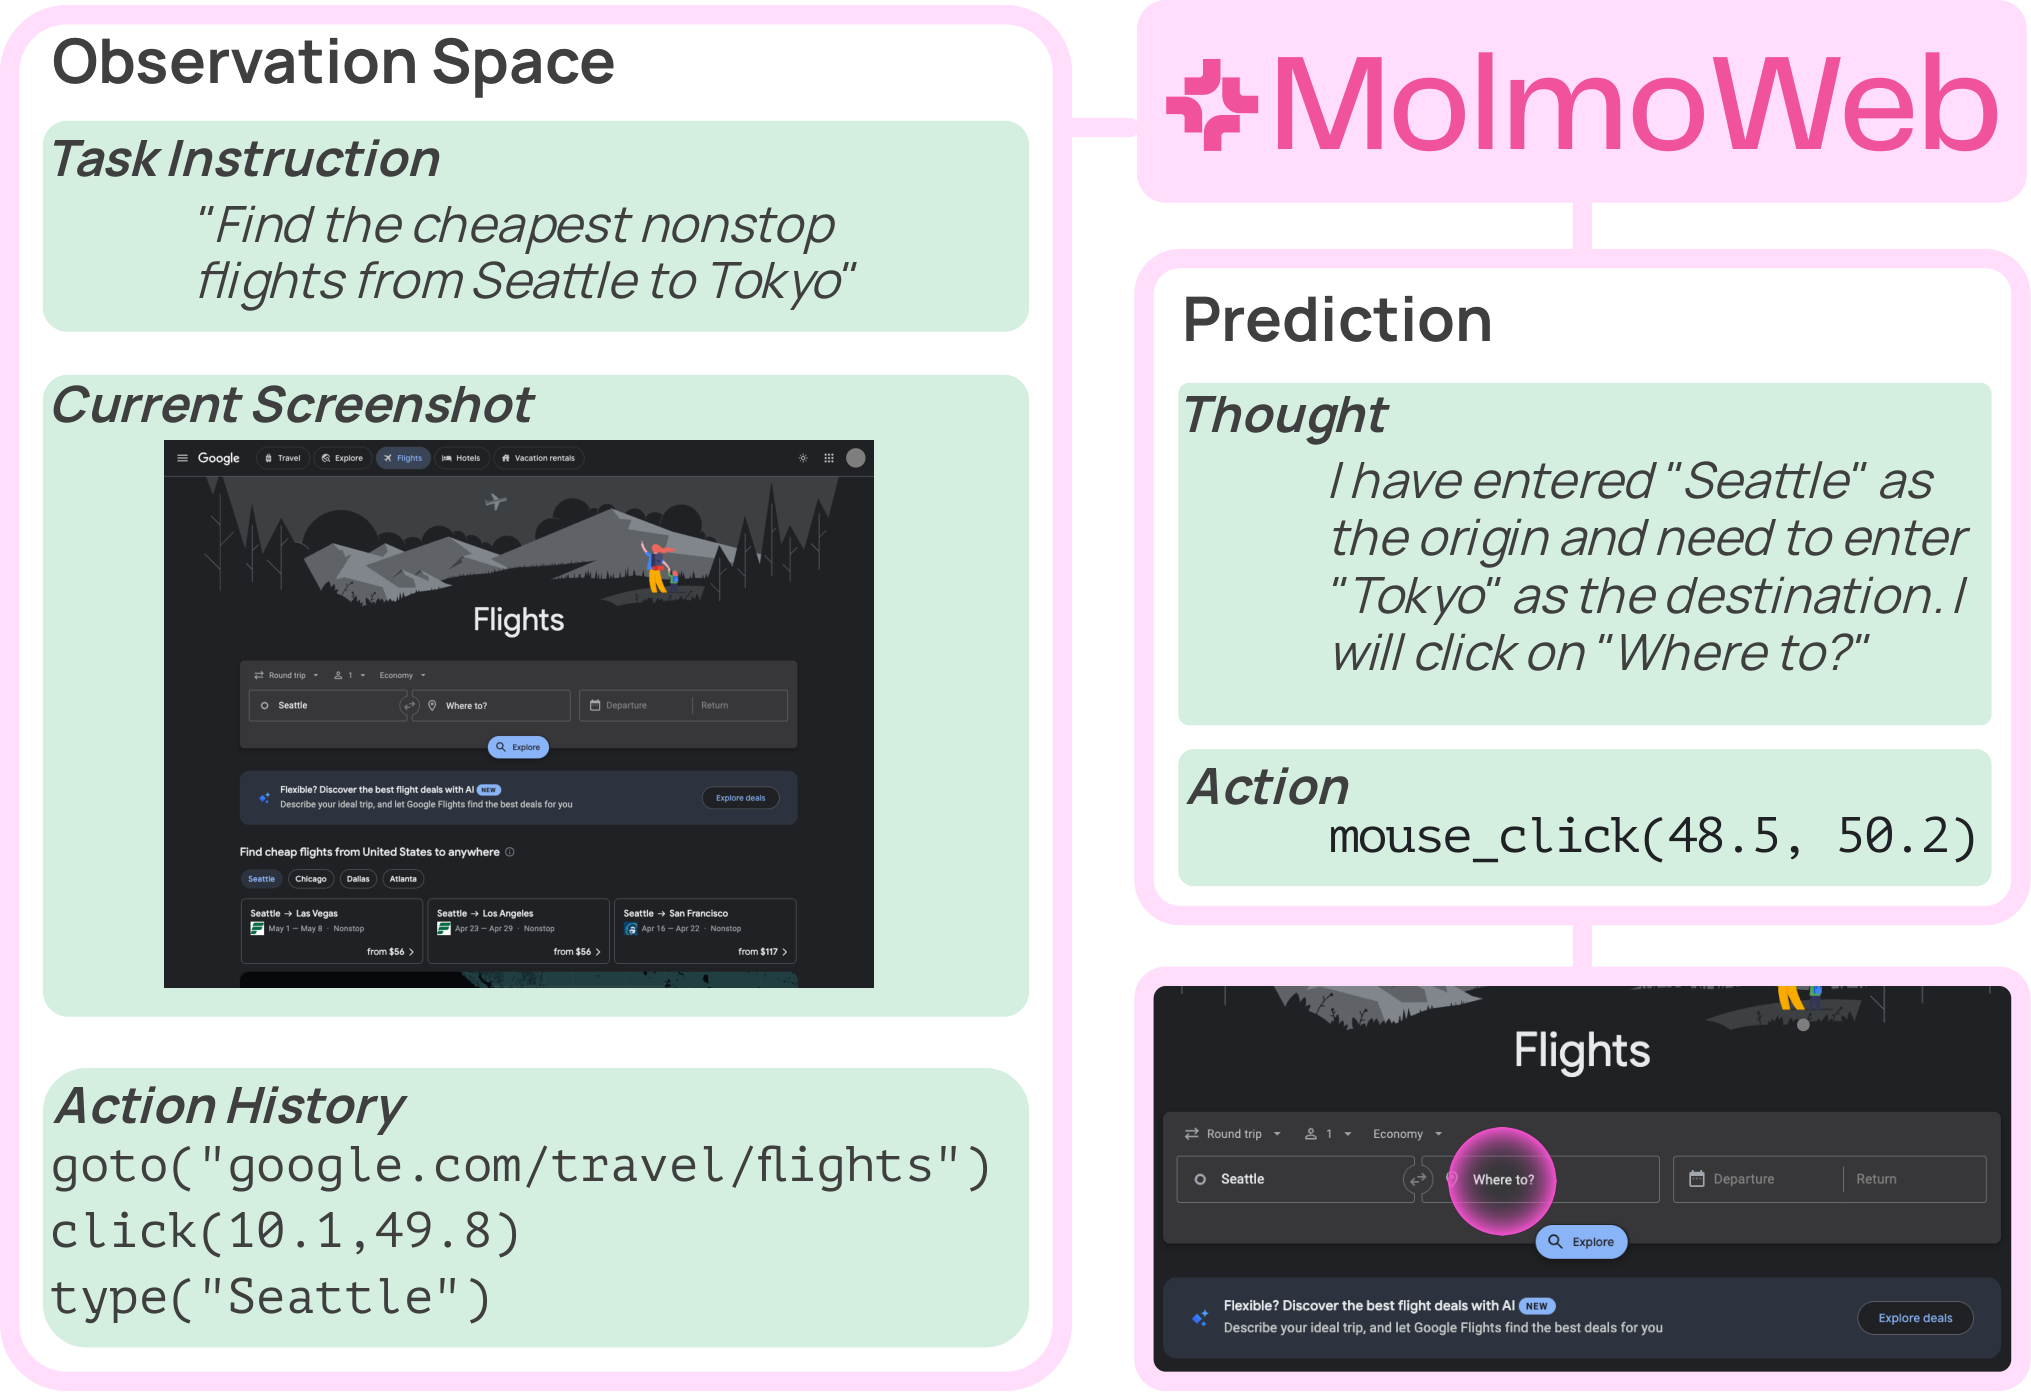
Choose which interaction history, page details, and screenshots a frozen MolmoWeb model sees to improve its next browser-action prediction.
Best score per runMacro action score (0–1)
00.654
Model · harness
Best
Submissions
Runtime
✳ Claude Opus 5Claude Code · max
0.6057
39
24.01 h
◎ GPT-5.6 SolCodex · xhigh
0.6053
40
24.01 h
Absolute macro action score over the same 948 held-out replay steps; higher is better. This measures next-action prediction, not live-browser task completion. Counts include every persisted Judge submission; runtime is the reported agent wall time.
All logged agent runs share one plot. Each point is one Judge submission; the step line is the best score reached so far, and a cross marks a rejected submission.
View by
The agent runs · 2 runs · submissionrunning bestbaseline · Judge measured▽ below 0.592Time since run start · points mark recorded Judge results
Find a better mix of textual history, page state, and visual context for a frozen MolmoWeb-4B model. The model predicts the next action from recorded browser steps; it is not trained or evaluated by completing live browsing tasks.
Environment
The frozen model, recorded browser trajectories, and read-only evaluation tools are provided.
The agent delivers one declarative strategy file describing what context the model receives.
Public proxy trajectories support local experiments; held-out trajectories remain concealed.
Work uses one GPU; the full Judge replay uses two GPUs on the same node.
Reference baseline
The shipped strategy uses recent textual thought/action history and the current screenshot, with no past screenshots. Under the fixed greedy replay protocol it scored 0.5966, reproduced by the first submission of both runs.
Every candidate is evaluated on the same held-out steps and receives an absolute score; a separate baseline is not rerun beside each candidate. The source project's live-browser success rates are not comparable to this offline replay score.
Research loop
Form a hypothesis about which past interactions or page details help predict the next action.
Edit the strategy and validate its schema and context budget.
Optionally test on the public proxy trajectories, then submit the closed strategy file.
Compare aggregate feedback by action type and refine the context choices.
What the agent may change
Which past interaction steps are selected and how much history is included.
Which thought, action, URL, and page-title fields appear in that history.
How thoughts, URLs, and historical actions are rendered or shortened.
Which past screenshots are included and at what resolution.
Which page-state and open-tab details are shown.
The current screenshot's crop allocation and the answer-length budget.
What stays fixed
The MolmoWeb model, its weights and processor, and greedy decoding.
The current screenshot, held-out replay steps, and reference interaction histories.
The action parser, coordinate conversion, output schema, and scoring rules.
The overall context limit, offline environment, and single-strategy-file interface.
No new executable code, model training, or additional data may be submitted.
Evaluation
The Judge evaluates all 948 held-out replay steps. It first averages graded prediction scores within each reference action type, then averages those action-type means equally. The resulting score lies between zero and one; higher is better.
Feedback includes overall and per-action aggregates, parsing validity, and context usage. Hidden trajectories, targets, predictions, and individual outcomes remain concealed. A strategy that violates the file, schema, or context constraints receives zero; an infrastructure failure receives no score.
Agent runs
Each figure is one run: a lollipop per submission, the running best as a step line, and a cross on the floor where a submission was rejected. Open the row below each figure for every Judge submission.
Claude Opus 5 · 39 submissions · best 0.6057 · ▽ below 0.592Claude Opus 5 — every submission, in order (39)
#
Score
1
0.5966
2
0.5983
3
0.5624
4
0.3101
5
0.5932
6
0.5889
7
0.5965
8
0.6057
9
0.5997
10
0.5934
11
0.6036
12
0.6040
13
0.6033
14
0.5973
15
0.6057
16
0.6013
17
0.5716
18
0.5721
19
0.6057
20
0.6057
21
0.5808
22
0.5617
23
0.6057
24
0.4778
25
0.2822
26
0.6057
27
0.5959
28
0.6057
29
0.5993
30
0.6057
31
0.4915
32
0.6057
33
0.5669
34
0.6057
35
0.6044
36
0.5867
37
0.6057
38
0.5770
39
0.6057
GPT-5.6 Sol · 40 submissions · best 0.6053 · ▽ below 0.592GPT-5.6 Sol — every submission, in order (40)