Choose a stronger training subset from a fixed web-data pool so the same CLIP model and training recipe perform better across DataComp's evaluation suite.
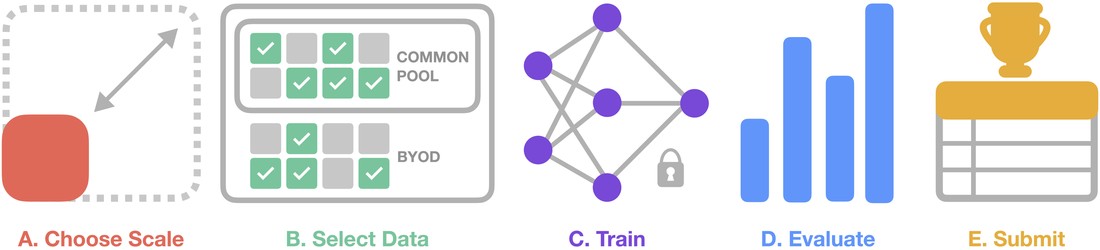
The task
Select a better subset of examples from the fixed successful web crawl so a fresh run of the same CLIP model performs better across DataComp's evaluation suite.
Environment
- The eligible crawl, public metadata, and image-text features are provided for research.
- The agent delivers a selected-example list together with provenance describing that selection.
Reference baseline
The official CLIP-score filtering recipe supplies a common starting selection. It is not retrained beside each candidate, so every logged result is an absolute score.
Research loop
- Study the public metadata, features, crawl coverage, and earlier aggregate feedback.
- Form a filtering hypothesis, materialize a valid selection, and check its provenance.
- Submit it for fresh training, compare the aggregate result, and revise the selection rule.
What the agent may change
- Which eligible training examples are selected.
- How public metadata and features are combined into a filtering rule.
- The size and composition of the selected subset.
- How the selection method is recorded in its provenance.
What stays fixed
- The eligible crawl and all source records.
- The CLIP model, training recipe, optimizer, and data budget.
- The evaluation suite, aggregation rule, Judge resources, and submission interface.
- Evaluation inputs and labels remain unavailable to the agent.
Evaluation
The Judge trains the fixed CLIP recipe from scratch on the submitted selection and reports the mean of the official scored metrics; higher is better. Feedback is aggregate, and an invalid selection does not receive a normal score.